Whilst you discover that a large proportion of your internet website online guests comes from bots, blocking them can truly really feel like the obvious next step. In some cases, the numbers do title for an instantaneous response.
PatronView simply in recent times documented 3.6 million requests hitting its website online in one day, with guests coming from more than 360,000 IP addresses. The site owner in the end built a slightly aggressive set of Cloudflare rules to get the guests underneath control.
We’ve seen immoderate cases on our private infrastructure, too. In our AI and bot visitors document, one crawler generated 3.75 million requests to add-to-cart URLs in 24 hours. Another repeating loop pattern drove quite a lot of millions of requests previous to we introduced a rule to catch it.
Those cases are exact, then again they don’t describe each and every internet website online.
In our newest research of more than 5,000 WordPress internet sites, AI bots accounted for merely 1.57% of bandwidth at the median site, in comparison with 17.8% at the 90th percentile and 90.3% at the 99th, while more than 1,000 internet sites recorded no AI-bot bandwidth the least bit.
That spread is why discovering AI bot guests and diagnosing an AI bot downside are two quite a lot of issues.
The decisions you’re making next can impact site potency, integrations, search visibility, and whether or not or no longer AI tools can ground your content material subject matter. Faster than changing the rest, you want to grasp what the bots are if truth be told doing.
Listed here are some mistakes we see site householders make after they skip that step.
Mistake 1: treating the proportion for the reason that research
If AI crawlers account for 20% of your site’s requests, that amount alone doesn’t assist you to know whether or not or no longer there’s a subject.
A large proportion of requests to cached articles would possibly place somewhat little energy on the application, while a smaller amount over and over again hitting search results, filtered product pages, or cart URLs can create far more artwork.
This is one explanation why network-wide bot statistics require some care when carried out to an individual site.
Our newest analysis found out that the indicate number of AI-bot requests in step with site ranged from 667 to 928 a day all through 4 measurements, in comparison with a median of merely 33 to 67 requests, while kind of 20% to 27% of internet sites won no AI-bot requests on a measured day.
In numerous words, a small team of workers of intently crawled internet sites pulls the average upward.
So if you happen to occur to be told that bots make up more than a part of web guests, or see any other site owner reporting 99% bot guests, don’t use that amount to make a decision what your individual site needs.
Get began with your individual guests.
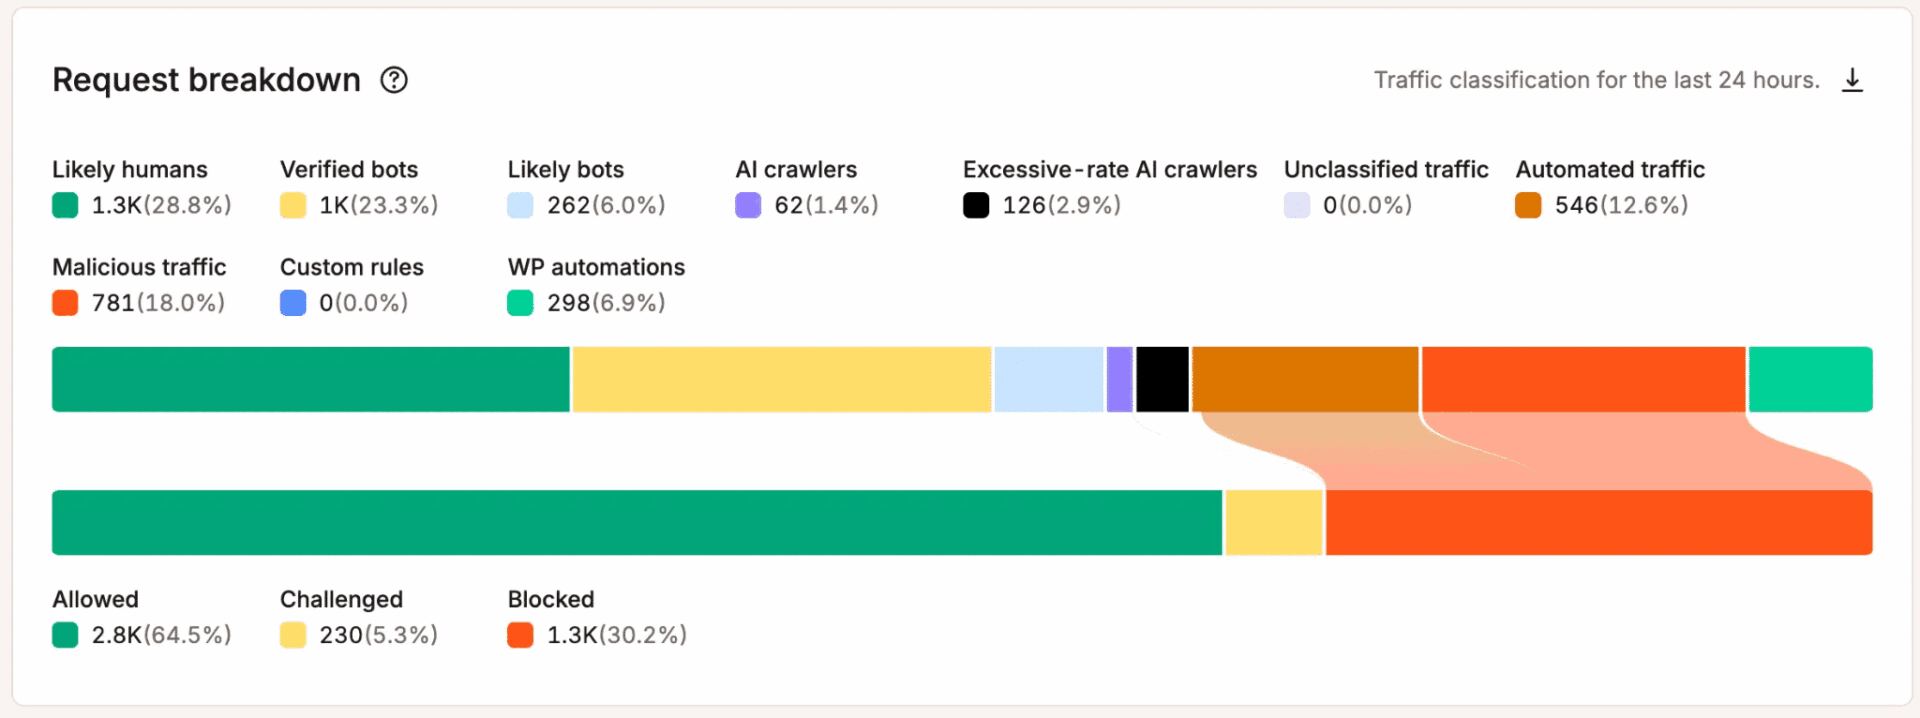
For Kinsta customers, the Bot coverage segment in MyKinsta displays how requests are being categorized, along side in all probability other folks, verified bots, in all probability bots, AI crawlers, excessive-rate AI crawlers, automated guests, and malicious guests.
You’ll then use Top guests to seem the paths, shopper agents, countries, and IP addresses behind a decided on guests sort.
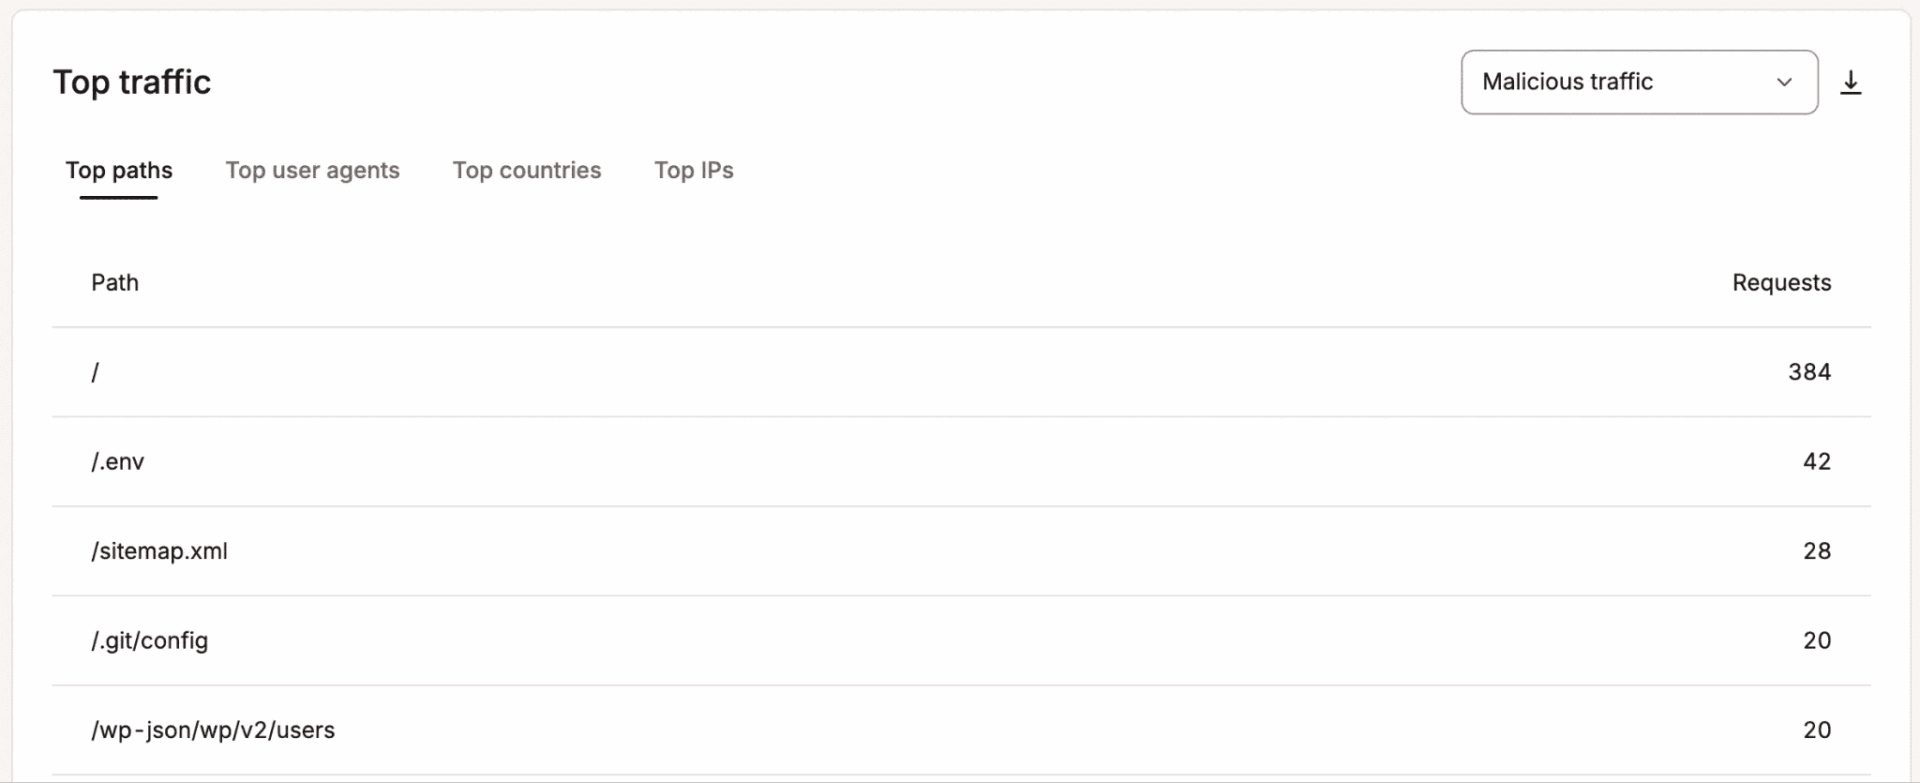
Faster than taking movement, you’ll have to be able to solution a few basic questions:
- How so much AI guests is if truth be told reaching the site?
- Which pages or endpoints is it soliciting for?
- Which crawlers, agents, or other automated systems are responsible?
- Is any of that guests affecting potency, bandwidth, PHP threads, or the enjoy of exact visitors?
Our latest file frames this as looking at the position, pattern, and profile of the guests. A site receiving very little AI guests with unusual request conduct would possibly need no movement, while one seeing sustained crawler guests against pricey dynamic URLs deserves a far closer look.
Mistake 2: blocking each and every bot given that guests is automated
The time frame “AI bot” now covers a variety of different sorts of guests. Some crawlers accumulate public content material subject matter for taste running against or AI search, while others fetch pages in step with a shopper’s request.
Those diversifications matter when making a decision what to allow. OpenAI, as an example, uses GPTBot for content material subject matter that can be utilized to fortify its models, while OAI-SearchBot helps make internet websites discoverable in ChatGPT search. Blocking OAI-SearchBot can because of this truth impact whether or not or no longer your content material subject matter turns out in ChatGPT search results.
Anthropic makes a identical distinction. ClaudeBot collects web content material subject matter that may contribute to taste running against, Claude-SearchBot is used for search, and Claude-Client can retrieve a internet website online when someone the usage of Claude asks for it.
Perplexity reports that PerplexityBot is used for its search index and Perplexity-Client for requests made in step with a shopper’s question.
Google provides publishers a separate Google-Extended control for the best way crawled content material subject matter can be used with Gemini. Google explicitly says changing that setting doesn’t impact inclusion or score in Google Search.
Putting all of the ones systems proper right into a single “AI” bucket throws away wisdom you’ll use.
Whilst you’d want not to fritter away site resources on taste running against, likelihood is that you’ll make a choice to restrict running against crawlers while leaving search and retrieval systems to be had. If your downside is an AI agent over and over again hitting a dynamic endpoint, changing your training-crawler protection gained’t unravel it.
There’s a industry question proper right here, too. Our consumer research found out that 44.7% of respondents discussed they continuously or extra steadily than no longer talk over with a company’s internet website online after receiving an AI recommendation. That doesn’t indicate AI crawler get entry to automatically produces referral guests, nevertheless it undoubtedly does indicate AI discovery is price allowing for previous to you’re creating a blanket selection about visibility.
At Kinsta, the Block AI crawlers control lets customers block AI crawlers, along side verified ones, without blocking standard search engine crawlers corresponding to Googlebot and Bing.

We moreover warn customers that blocking AI crawlers can scale back visibility in AI-powered search results, summaries, or ideas.
Mistake 3: treating each and every AI crawler spike as a security emergency
Bots can create issues of safety through brute-force makes an strive, DDoS attacks, credential attacks, and other abusive automation, then again a verified AI crawler sending too many dependable requests is a novel kind of downside.
All over our bot visitors reside tournament, Kinsta CTO Daniel Pataki outlined why he worries about one of the best ways site householders answer when those two problems get combined together:
“I fear overreaction in this case more than I fear underreaction because of it isn’t a security issue.”
He was once as soon as talking regarding the wider AI crawler downside, where numerous the harsh guests we’re seeing comes from dependable systems crawling inefficiently fairly than an attacker having a look to compromise the site.
The response changes when the site is already suffering. If bots are tying up server resources, slowing pages, or fighting exact customers from the usage of the site, stabilizing the site comes first. Daniel recommended temporarily blocking bot guests when it’s causing an energetic downside, then investigating as quickly because the site is underneath control.
The mistake is turning that emergency measure into a long lasting protection without learning what came about.
Kinsta’s Bot Coverage will give you a variety of levels of control, from baseline protection against malicious guests to blocking automations or tricky in all probability bots when stricter protection is sought after. Excessive-rate AI crawlers can also be challenged at the appropriate protection levels.

A shocking potency incident would possibly justify stronger controls in this day and age. As quickly because the incident has passed, check out what was once as soon as hitting the site and whether or not or no longer those stronger controls however make sense.
Mistake 4: having a look at request amount while ignoring where the requests pass
Our infrastructure data makes this difference easy to seem. A request for a cached blog publish and one for an uncached WooCommerce search internet web page each and every depend as a single request, even though the second can require far more server artwork.
This can be a demonstration from the bot visitors fact take a look at reside tournament:
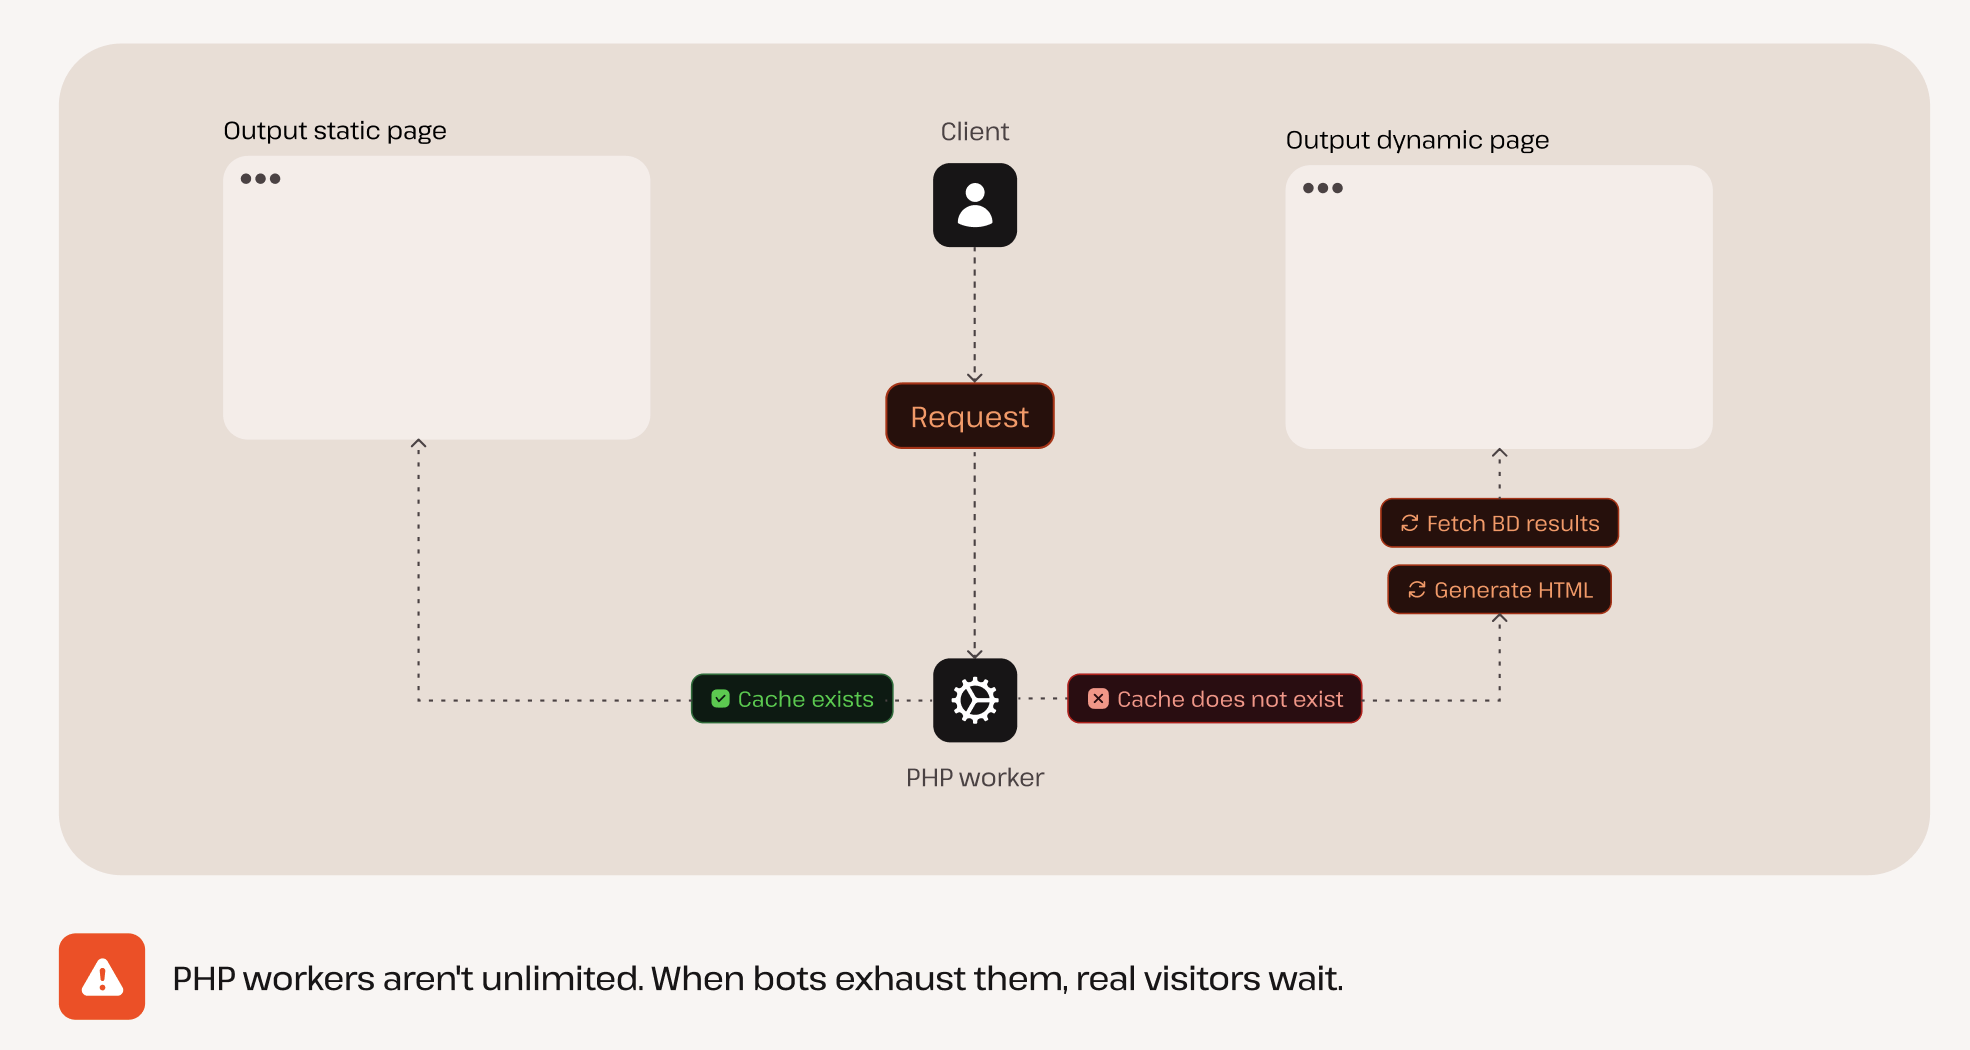
When a cached internet web page is available, WordPress can maintain numerous the request without regenerating the internet web page.
A dynamic request would possibly desire a PHP thread (also known as a worker), database queries, internet web page generation, and infrequently session coping with previous to WordPress can return the rest. Cart and checkout process can add further artwork.
Now repeat that process 1000’s of circumstances.
Right through 3 measurements in our newest find out about, between 76.9% and 90.5% of AI crawler requests went to dynamic content material subject matter. Human guests stayed between 18.3% and 18.9%.
That difference tells you much more about conceivable infrastructure energy than a raw request depend.
Consider the add-to-cart incident we found in our AI bot visitors analysis. One crawler generated 3.75 million requests in 24 hours, kind of one request each and every 23 milliseconds. Each request would possibly make WordPress perform artwork for a “buyer” who was once as soon as on no account going to buy the rest.
This can be why two internet sites with the equivalent share of AI guests can behave very in a different way.
A content material subject matter site where crawlers maximum recurrently request cached articles would possibly maintain a large amount without a lot hassle, while a WooCommerce store can truly really feel the impact so much quicker if even a smaller number of requests over and over again hit search, filters, cart actions, account pages, or other uncached routes.
Whilst you discover a spike, look earlier the shopper agent.
In MyKinsta, you’ll filter out Top guests via AI crawlers and check out the paths they request most incessantly.

Then review that with cache wisdom, server bandwidth, and serve as data to seem whether or not or no longer those requests are reaching the application and rising artwork.

Seeing GPTBot or any other crawler at the top of a file is useful. Seeing that 1000’s of its requests are going to /blog/ tells you one thing. Seeing them pass to search around results or a parameterized WooCommerce URL tells you something else.
Mistake 5: blocking the crawler and leaving the transfer slowly trap behind
Each so steadily the bot is most efficient the thing that exposes a subject already sitting to your URL building.
WordPress internet sites can generate a lot of URLs from query parameters, search pages, filtered archives, pagination, calendars, product diversifications, and ecommerce actions.
A person would possibly recognize that two slightly different URLs lead to essentially the equivalent internet web page, while a crawler simply sees further links to look at.
If each and every internet web page produces any other set of URLs that appear new, the crawler can keep following them. That is how you end up with patterns that look much more aggressive than somebody intended.
We spotted this in our previous infrastructure analysis. One repeating pattern become sufficiently big {{that a}} single rule designed to catch it filtered 550 million requests in 30 days.
Blocking the crawler would possibly prevent the fast load, nevertheless it undoubtedly doesn’t remove the URL pattern that resulted in the crawler to look out new pages.
When a decided on path rapidly dominates AI crawler guests, check out the path itself:
- Is WordPress generating massive numbers of parameter combinations?
- Can a crawler keep transferring through calendar or pagination URLs indefinitely?
- Are search and filter out pages exposing 1000’s of URL diversifications?
- Are movement URLs corresponding to add-to-cart links crawlable after they don’t want to be?
- Does each and every URL being generated want to exist and be discoverable?
You must nonetheless make a decision to block or downside the crawler, then again first understand what saved bringing it once more.
This is specifically important for corporations. If a variety of consumer internet sites use the equivalent plugin, WooCommerce configuration, theme, or URL pattern, an aggressive crawler can disclose the equivalent issue all through a couple of site. Fixing the conduct may also be further useful than maintaining an ever-growing checklist of bot names.
Mistake 6: assuming robots.txt has stopped the guests
A robots.txt alternate may also be the right kind response when you want to tell a reputable crawler not to get entry to phase or your whole site, then again you proceed to pray to try the guests shortly.
robots.txt will depend on the crawler honoring the instruction and doesn’t physically prevent the request from reaching your site.
We’ve covered this distinction in detail in our information to AI crawlers. robots.txt communicates transfer slowly preferences, while llms.txt provides a structured content material subject matter index for tools that make a choice to be told it. Enforcement happens elsewhere.
This problems after discovering a potency downside, because of merely bettering a report may make you’re feeling like the problem has been handled.
Check your logs or bot analytics. If requests from the crawler fall after your robots.txt alternate, you’ve got evidence that it worked. If the guests continues, otherwise you may well be dealing with any other automated tool that doesn’t practice the instruction, you want an enforcement control.
The equivalent applies when your downside is request worth fairly than get entry to itself. A crawler could also be allowed to be told your content material subject matter and however request it at a value your site can’t very simply serve.
Mistake 7: copying any other site’s firewall rules without checking what they may block
The PatronView instance is useful given that site’s response was once as soon as based on its own data.
Its target audience is overwhelmingly in North America, so the owner hard scenarios guests coming from other continents. He checked his exact buyer data previous to tricky consumers with old-fashioned browser diversifications. He moreover presentations what selection of challenged visitors if truth be told complete the issue. In one period, most efficient 0.24% of more than 100,000 hard scenarios were solved.
Those numbers make the foundations easier to justify for that site, then again applying the equivalent setup to a global e-commerce store would possibly in any case finally end up tricky dependable customers. The equivalent probability turns out when teams stack a variety of protection tools because of each and every one seems useful on its own.
A WordPress site can have hosting-level bot protection, Cloudflare rules, a security plugin, worth limiting, country blocks, and custom designed WAF rules all making alternatives concerning the equivalent request. Debugging a false sure becomes much more tricky whilst you don’t know which layer made the decision.
For Kinsta customers, we specifically recommend against combining Kinsta Bot Coverage with further customized bot coverage layers. Conflicting classifications may motive dependable visitors or integrations to be blocked.
Higher protection levels can also impact dependable automation corresponding to APIs, monitoring tools, webhooks, and WordPress integrations. MyKinsta because of this truth accommodates an Allow same old WordPress automations selection and always-allow exceptions for trusted IP addresses, paths, and shopper agents.

Whilst you run an corporate, a typical process is further useful than a typical rule set. You’ll use the equivalent process all through 20 consumer internet sites via working out the guests, examining its paths, checking potency, choosing a control, testing it, and monitoring the outcome.
What to do whilst you discover AI bot guests
Get began with what’s going on on your site. If bot guests is affecting exact visitors, offer protection to the site first, then check out how so much guests you may well be receiving, which paths it reaches, and which systems are responsible.
From there, make a choice the smallest alternate that solves the problem. That might indicate updating robots.txt, blocking or tricky a crawler, fixing a crawlable URL pattern, or doing no longer anything else if the guests isn’t causing harm.
Kinsta customers can do numerous this investigation directly in MyKinsta. Bot visitors analytics separates AI crawlers, excessive-rate AI crawlers, verified bots, automated guests, and other request varieties, while Top guests displays the paths, shopper agents, countries, and IPs behind them.
You’ll moreover review that process with cache habits, server bandwidth, and PHP efficiency to seem whether or not or no longer the guests is if truth be told pressuring your site previous to deciding what to block.
The publish The 7 greatest errors website online house owners make after finding AI bot visitors appeared first on Kinsta®.
0 Comments